Source painting
MAPR 2026
ViFA-Council Multi‑Agent LLM Deliberation for Vietnamese Folk Art Generation
1University of Science, Ho Chi Minh City, Vietnam
2Vietnam National University, Ho Chi Minh City, Vietnam
3University of Information Technology, Ho Chi Minh City, Vietnam
†Corresponding author
Abstract
This paper presents ViFA-Council, a three-stage multi-agent framework that employs multiple large language models (LLMs) to tackle two culturally complex generative tasks: image outpainting and educational story generation based on traditional Vietnamese folk paintings.
Current single-model generative pipelines frequently struggle with stylistic hallucinations and cultural misrepresentations because they lack mechanisms for cross-model critique. ViFA-Council addresses this challenge by orchestrating collaboration among GPT-4o, Gemini 3.1 Pro, and Claude Sonnet 4.6. It enforces rigorous cultural constraints through structured agent deliberation. This deliberation is mediated by task-specific JSON schemas that effectively bridge natural language discussions with diffusion-based image synthesis using Banana Pro.
Experiments and a user study demonstrate that structured multi-agent deliberation is a promising direction for improving cultural fidelity and narrative coherence in culturally sensitive, low-resource artistic domains.
Method
A three-stage Council that drafts, cross-refines and adjudicates
Given a folk painting I and a user directive q, the Council produces one Chairman-selected JSON configuration J*. Every stage reads and writes the same task-specific schema, so cultural and stylistic constraints are tightened before any image is generated.
-
Parallel drafting
GPT-4o, Gemini 3.1 Pro and Claude Sonnet 4.6 each fill the schema from the same painting and directive, without seeing one another’s output. Calls run concurrently with exponential-backoff retries.
3 independent drafts -
Cross-model refinement
Every agent reviews and improves every draft, whoever wrote it: checking structural validity, improving cultural fidelity, and returning the same schema. A failed call falls back to the original draft, so no candidate is lost.
up to 3 × 3 = 9 refined candidates -
Chairman adjudication
A separate Gemini 3.1 Pro instance, isolated from the earlier stages, receives all drafts and refinements under alphabetical labels. It scores structural validity, logical coherence, cultural fidelity and whether refinement helped, then names one winner.
1 selected configuration J*
| Task | Field | Description | Purpose |
|---|---|---|---|
| Outpainting | input_image_analysis | Original style and dominant colors | Source-aware visual analysis |
| Outpainting | expansion_settings | Direction, pixel amount, and mask blur | Synthesis spatial control |
| Outpainting | seamless_blending | Style, texture, color, pattern constraints | Boundary and appearance continuity |
| Outpainting | outpainting_scenarios[] | Expansion proposals with prompts | Multi-candidate generation |
| Story | source_material | Title, era, cultural context, and symbols | Cultural grounding |
| Story | art_style_preservation | Character, line, and perspective constraints | Prevent visual-style drift |
| Story | characters[] | Appearance, style, and cultural significance | Cross-panel character consistency |
| Story | story_panels[] | Layout, dialogue, motifs, and transitions | Sequential narrative specification |
| Story | educational_content | Objectives, explanations, and glossary | Educational adaptation |
Task 1
Folk-painting outpainting
We compare ViFA-Council against GPT-4o, Gemini 3.1 Pro and Claude Sonnet 4.6, each prompted with the identical Stage 1 instruction but without cross-refinement or Chairman adjudication, and rendered through the same image pipeline. Experiments use a curated collection of 257 paintings: 112 Đông Hồ, 74 Hàng Trống and 71 Kim Hoàng works.
-
GPT-4o
Typographical content injection
Modern Vietnamese text is written straight onto the canvas, such as “VƯỜN NHÀ BÌNH YÊN” and “BÉ VUI ĐÙA”.
-
Gemini 3.1 Pro
Cultural hallucination
Imperial swirling clouds, ornamental rock gardens and curved-roof pagodas replace naive rural aesthetics with generic East Asian tropes.
-
Claude Sonnet 4.6
Textural and chromatic degradation
Boundaries are structurally plausible, but the earthy palette is flattened and the fibrous texture of giấy điệp paper is lost.
-
Gemini 3.1 Pro, stories
Structural format drift
Comic panels morph into modern educational infographics with rigid typographic headers.
| Model | CLIP ↑ | LPIPS ↓ | DreamSim ↓ | JSON Semantic (%) ↑ |
|---|---|---|---|---|
| GPT-4o | 0.8348 | 0.7832 | 0.5896 | 70.10 |
| Claude Sonnet 4.6 | 0.8485 | 0.7986 | 0.6169 | 84.30 |
| Gemini 3.1 Pro | 0.8520 | 0.7705 | 0.6134 | 76.70 |
| ViFA-Council (ours) | 0.8524 | 0.7317 | 0.5745 | 93.90 |
More outpainting results
Pick a painting to see the source beside the ViFA-Council extension.
Source · Đông Hồ
ViFA-Council
Source · Đông Hồ
ViFA-Council
Source · Đông Hồ
ViFA-Council
Source · Đông Hồ
ViFA-Council
Source · Đông Hồ
ViFA-Council
Source · Đông Hồ
ViFA-Council
Source · Đông Hồ
ViFA-Council
Source · Đông Hồ
ViFA-Council
Task 2
Educational story generation
The same Council turns a single painting into a multi-panel comic for children: characters stay consistent with the source print, dialogue is written in Vietnamese, and the story carries the painting’s cultural lesson. The baseline is Gemini 3.1 Pro with the Stage 1 instruction alone.
| Model | CLIP ↑ | DINO ↑ | PickScore ↑ | JSON Semantic (%) ↑ |
|---|---|---|---|---|
| Gemini 3.1 Pro | 0.667 | 0.504 | 18.573 | 87.0 |
| ViFA-Council (ours) | 0.703 | 0.601 | 19.61 | 93.0 |
Story pages from ViFA-Council
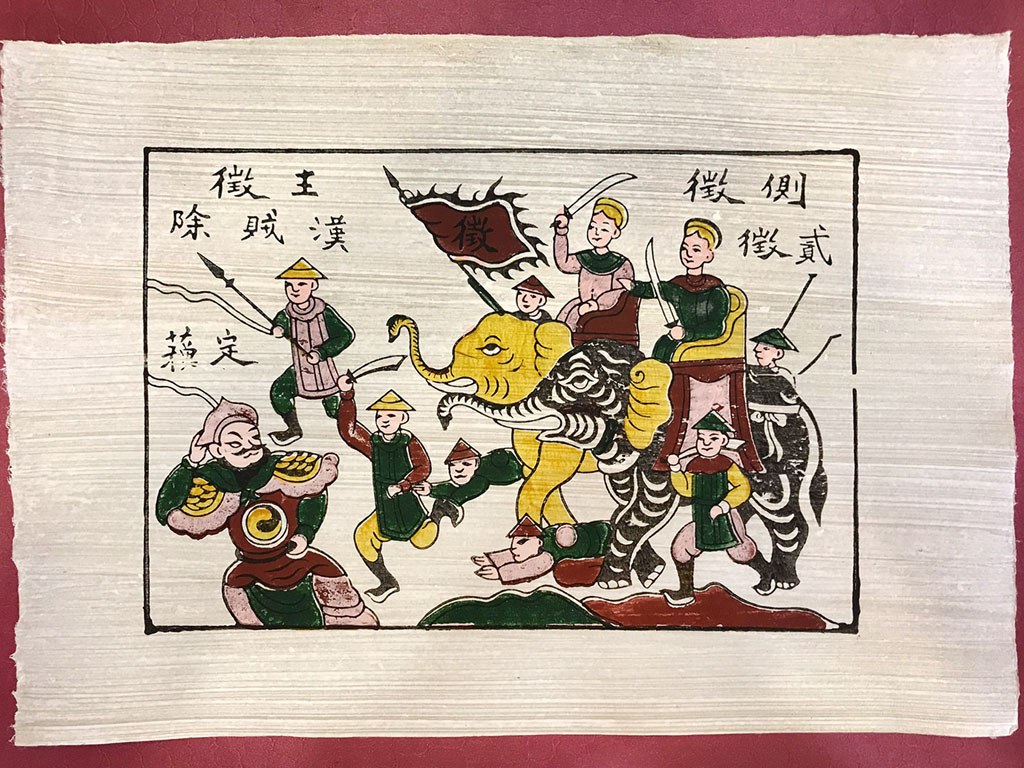
Hai Bà Trưng đánh giặcSource: Đông Hồ print
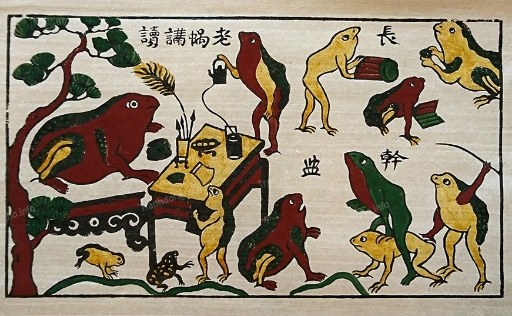
Thầy đồ CócSource: Đông Hồ print
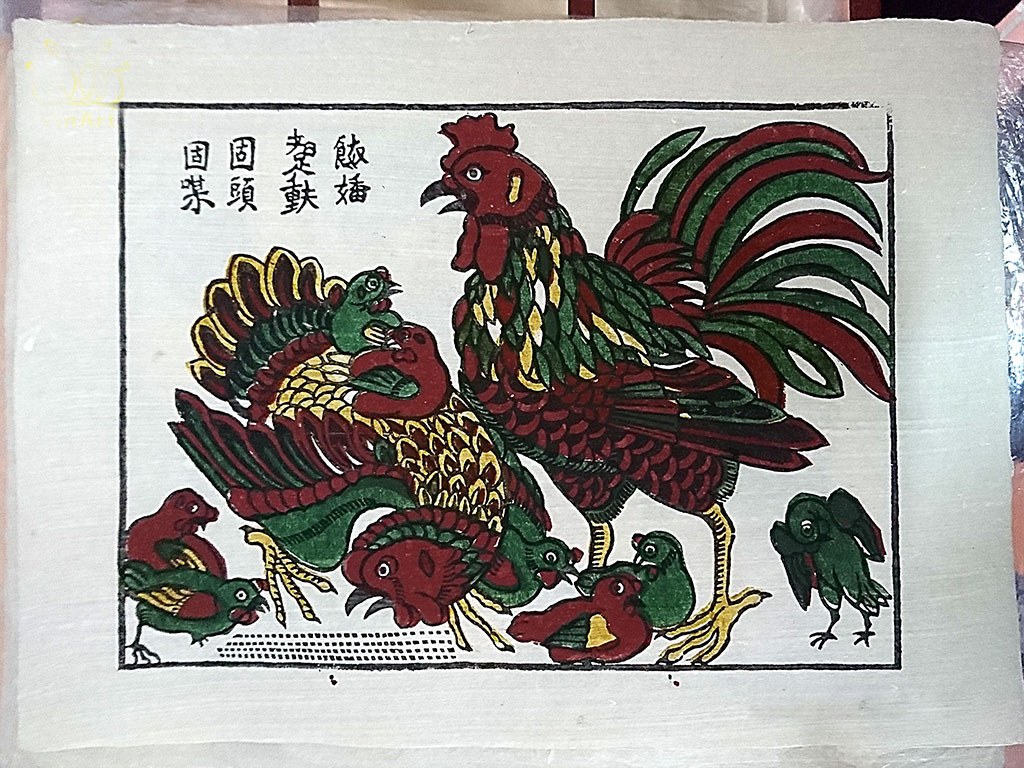
Gà thư hùngSource: Đông Hồ print
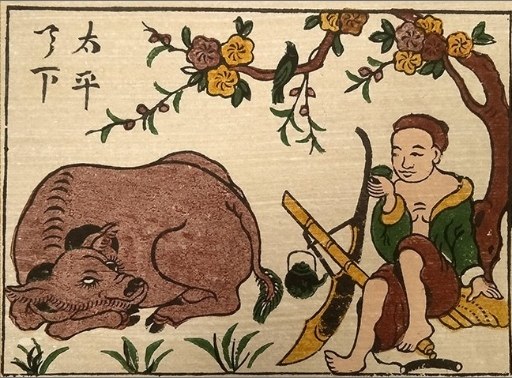
Nông nhànSource: Đông Hồ print
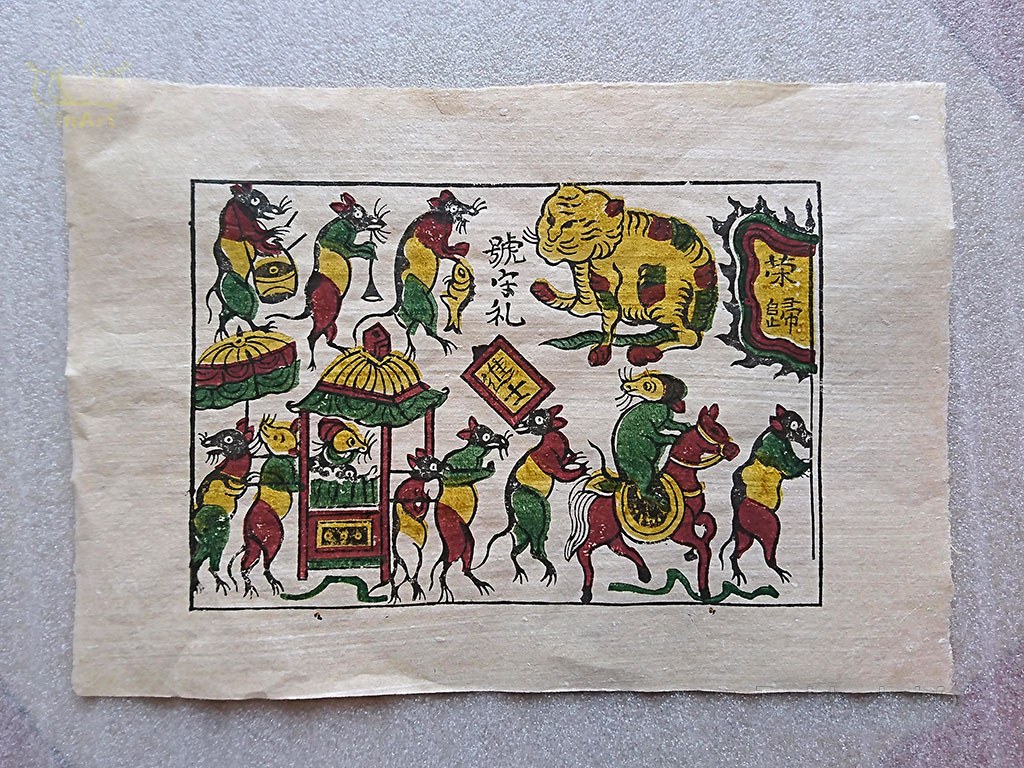
Đám cưới chuộtSource: Đông Hồ print
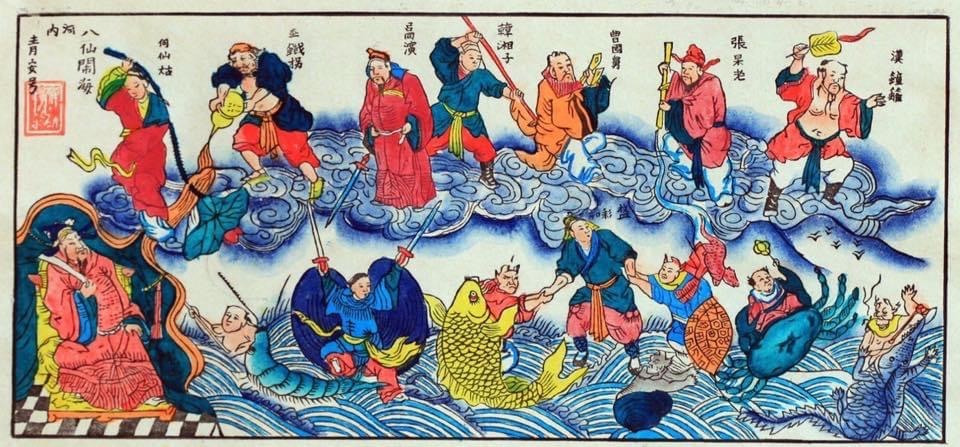
Bát tiên náo hảiSource: Hàng Trống painting
Select a page to enlarge it.1 / 6
User study
Blind ratings from 15 participants
Ten STEM students, three educators and two AI engineers rated anonymized results in randomized order on a five-point Likert scale. ViFA-Council receives the highest overall rating on both tasks, with the lowest variance. For stories, the largest gains are in dialogue quality (3.96 vs. 3.54) and narrative coherence (3.94 vs. 3.66).
| Method | Blend | Style | Culture | Overall |
|---|---|---|---|---|
| GPT-4o | 3.18 | 3.42 | 3.52 | 3.37 ± 1.16 |
| Gemini 3.1 Pro | 3.36 | 3.48 | 3.55 | 3.46 ± 1.11 |
| Claude Sonnet 4.6 | 3.95 | 3.64 | 3.96 | 3.85 ± 1.00 |
| ViFA-Council | 4.08 | 4.08 | 4.00 | 4.05 ± 0.89 |
| Method | Culture | Narrative | Dialogue | Overall |
|---|---|---|---|---|
| Gemini 3.1 Pro | 3.56 | 3.66 | 3.54 | 3.59 ± 1.05 |
| ViFA-Council | 3.89 | 3.94 | 3.96 | 3.93 ± 0.88 |
Limitations
ViFA-Council is evaluated zero-shot, without fine-tuning on Vietnamese folk-art data, which may limit adaptation to subtle school-specific conventions. The user study measures perceived cultural relevance and does not include professional folk-art historians or artisans, so historical and iconographic authenticity still needs expert assessment. The framework depends on the underlying LLMs and image model, and its multiple parallel API calls cost more and take longer than single-model generation.
Citation
BibTeX
@inproceedings{Dang2026MAPR,
  title     = {ViFA-Council: Multi-Agent LLM Deliberation for Vietnamese Folk Art Generation},
  author    = {Nguyen, Hai-Dang and Pham, Minh-Phuong and Dao, Thao Thi Phuong and Do, Trong-Le and Nguyen, Vinh-Tiep and Le, Trung-Nghia},
  booktitle = {International Conference on Multimedia Analysis and Pattern Recognition (MAPR)},
  year      = {2026}
}
Acknowledgment
This research is funded by Vietnam National University - Ho Chi Minh City (VNU-HCM) under Grant Number B2026-18-17.